-
AI Capability Server
An AI server is designed to run artificial intelligence workloads such as model training and inference. These systems support compute-intensive applications including large language models (LLMs), generative AI, computer vision, natural language processing, and advanced analytics. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before. This is where AI server clusters stand out, crafted for. Building and setting up your very own high-performance local AI server offers a fantastic solution to this. Network Engineer and tech enthusiast. Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best. They provide the hardware environment —. Lenovo's broad portfolio of ThinkEdge and ThinkSystem servers enable you to accelerate and scale AI solutions efficiently while managing and protecting all your data.
[PDF Version]
-
Saudi Arabian manufacturer of AI server LPO
HPE's latest 'Saudi Made' ProLiant servers, powered by AMD EPYC processors, mark a new phase in local manufacturing—enhancing performance, data resilience, and the Kingdom's AI ambitions. Saudi Arabia's technology ambitions are no longer about simply adopting innovation — they're. At HPE, we combine unified data, AI, and edge-to-cloud expertise with deep collaboration to bring transformative solutions to life. This initiative, a. HPE is set to return to LEAP, taking place at the Riyadh International Convention and Exhibition Centre in Malham, Saudi Arabia from February 09 – 12, 2025. At the event, HPE will showcase its cutting-edge AI, hybrid cloud and networking solutions, including HPE Private Cloud AI, and announce its. HPE and AMD launch the first Saudi-made ProLiant servers at alfanar's Riyadh facility, delivering faster performance, stronger security, and digital sovereignty to power AI, cloud, and Vision 2030 goals across the Middle East.
[PDF Version]
-
AI server 3090
May 2026 picks: 2x RTX 3090 (48GB) for the dense-model workhorse; 2x RTX 5060 Ti 16GB (32GB) for budget MoE with --cpu-moe; 2x RTX 2080 Ti 22GB modded for value (Qwen 3. 6 27B at 38 tok/s); 1x 3090 + 1x 4090 for mixed-card pipeline parallelism. cpp and Ollama handle. Want to build a GPU home server for running quantized models? Here's some tips and tricks for setting up the server. RTX 3090: Two RTX 3090s with NVLink are a common choice for running large AI models. Previously I have built one but only for mining where those GPUs were connected via PCIE x1 risers. 0 x16 so the thing looks slightly different. Building a full DIY rig is a high base cost with inflation with every new recent dual slot capable motherboard checking in above $100. AI from The Basement: My latest side project, a dedicated LLM server powered by 8x RTX 3090 Graphic Cards, boasting a total of 192GB of VRAM. This blogpost was originally posted on my LinkedIn profile in July 2024. Backstory: Sometime in. A 70B model that can't fit on one 24GB card runs at 16-21 tok/s across dual RTX 3090s. You need server-grade platforms.
[PDF Version]
-
AI Server Heat Dissipation Industry Analysis
This analysis explores how AI is transforming thermal management, the impact of advanced cooling technologies—including air, liquid, and Direct-to-Chip cooling—and the critical balance between compute density and thermal efficiency to future-proof data centers. Liquid cooling is essential for AI-driven data centres, efficiently managing the extreme heat generated by high-density AI server racks., GPUs) used for training LLMs (large language models) and inference workloads, generate enough heat to necessitate liquid cooling. The PowerCool eRDHx is Dell's new rack scale liquid cooling innovation that ensures 100% of the heat in the rack is collected to warm water (up to 32. Liquid cooling of AI servers does not require a fundamental change to facility water systems (FWS), but the cooling systems will need to evolve to support both liquid- and air-cooled requirements that will exist in a hybrid environment. The Growing Challenge of Thermal.
[PDF Version]
-
Setting up Xiaozhi AI Server
This document provides instructions for deploying the xiaozhi-server platform. For setting up a local development. XiaoZhi AI is an open-source intelligent voice robot based on ESP32-S3 development, integrating wake word detection, AI conversation, device control, and multi-protocol communication capabilities. com/xinnan-tech/xiaozhi-esp32-server to deploy a local server and establish a connection with the ESP32 S3 WROOM. If you encounter any bugs in the code during use, please submit an issue at. Use a mobile phone or computer to connect to the device's WiFi network: Xiaozhi-xxxxxx. Through this project, we aim to help more people get started with AI hardware development and understand how to implement rapidly evolving large language models in. This page guides you through the initial deployment of xiaozhi-server, from prerequisites to a running system. It covers the quickest paths to get both the manager-server (control plane) and backend-server (speech processing) operational, along with verification steps to confirm proper.
[PDF Version]
-
AI Server Liquid Cooling Principle
Cold plate liquid cooling transfers the heat from high-power components (like AI chips) indirectly to a fluid via a metal plate. The heat passes through the metal into the liquid, which then flows out of the server to exchange heat with an external source. Water is the most commonly. In today's AI engines, heat leaves little room for error — a small temperature swing can be the difference between sustained performance and throttling. In modern data centers, this margin is no longer theoretical. Data. Liquid cooling involves using flowing water or liquid refrigerants to absorb and carry away the heat generated by equipment, rather than relying on air circulation. This AI revolution is built on incredibly powerful computer chips. But there's a catch, a hot one. These chips, especially the GPUs that are the workhorses of AI, are generating a staggering amount of heat.
[PDF Version]
-
AI upstream server manufacturers
While semiconductor giants like NVIDIA and AMD develop the hardware that powers AI servers, specialized AI companies like TensorWave, Lambda Labs, and Cerebras Systems are redefining AI and HPC performance with custom-built servers. So, which company leads in AI chip manufacturing?Artificial Intelligence (AI) server manufacturers have experienced surging demand as data center operators require significantly more computing power than before the advent of ChatGPT and other Generative Artificial Intelligence (Gen AI) tools. Enterprises are investing billions of dollars in cloud. These massive computing needs have given rise to a new breed of technology providers: AI server companies. Every AI breakthrough, from self-driving cars to LLMs, depends on ultra-fast servers crunching numbers behind the scenes. 3 Billion by 2035, at a CAGR of 40. 06% during the forecast period 2025–2035. (US), Hewlett Packard Enterprise Development LP (US), Lenovo (Hong Kong), Huawei Technologies Co. These companies offer AI servers with powerful GPUs, TPUs, and specialized hardware to accelerate machine learning, deep learning, and data processing tasks.
[PDF Version]
-

What is a professional-grade AI server
AI servers are high-performance computing systems designed to process complex artificial intelligence workloads, including large-scale model training and real-time inference. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before. They provide the hardware environment —. Artificial Intelligence (AI) server manufacturers have experienced surging demand as data center operators require significantly more computing power than before the advent of ChatGPT and other Generative Artificial Intelligence (Gen AI) tools. Enterprises are investing billions of dollars in cloud. Modern AI models are data-hungry, computation-heavy beasts that need specialized hardware just to function, let alone perform at their best.
[PDF Version]
-

AI computing power optical module
Optical modules convert electrical signals into light to move data quickly and reliably in AI systems, enabling fast and smooth data processing. Although co-packaged optics (CPO) and on-board optics (OBO) have been proposed to increase bandwidth density, these approaches introduce significant challenges in field serviceability, scalability, and manufacturability, making them difficult to deploy widely in hyperscale environments. Understanding their role is key to building efficient, scalable AI systems. Yole Group attended OFC 2026 with a dedicated team of analysts on site, actively engaging with major players in the photonics. The widespread adoption of AI large-scale models, represented by ChatGPT, will drive a rapid increase in computational power demand. In this process, the server industry chain will become a crucial beneficiary.
[PDF Version]
-
Jointly developing AI server with Paraguay
Paraguay and the Republic of China (Taiwan) have announced a landmark cooperation agreement to develop one of the world's largest centres for Artificial Intelligence infrastructure. The announcement followed Peña's May visit to Taiwan and meetings. Breaking: Paraguay is positioning itself as the unexpected tech giant of South America, attracting hundreds of millions in AI infrastructure investments. Here's why global tech companies are racing to this landlocked nation—and what it means for your future in Paraguay. In a stunning development. Taiwan President Lai Ching-te and Paraguayan President Santiago Peña (left center) jointly witnessed Foreign Minister Lin Chia-lung (right) and Paraguayan Foreign Minister Rubén Ramírez Lezcano (left) sign a 'Memorandum of Understanding on Cooperation in the Investment of a Sovereign AI Computing. President Santiago Peña emphasized this Wednesday that the alliance forged with Taiwan during his recent trip to the island, for the construction of one of the world's largest AI centers, positions Paraguay in the global race for the development of this technology, given its status as a leader in.
[PDF Version]
-
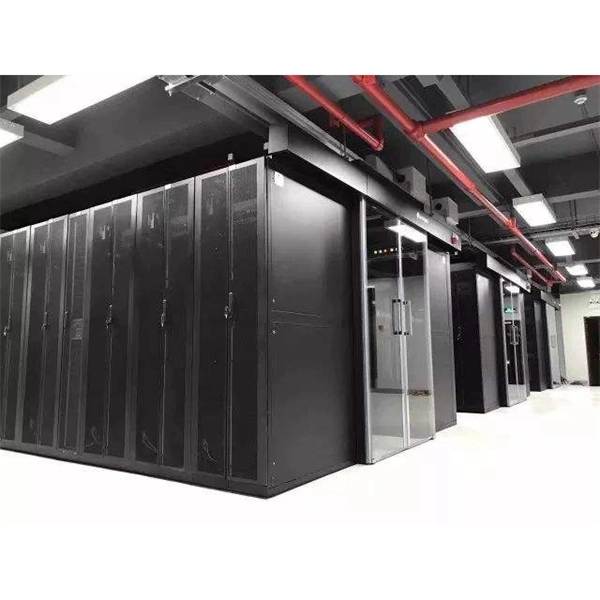
How to configure an enterprise server rack network
Learn how to rack a server with this detailed step-by-step guide. Includes setup tips, cable management, cooling, and safety practices. When designing a data center, the first step is to choose the right type of rack for your particular use case. In this article, you will learn how to rack a server, and get some useful tips and. Use sliding rails to mount servers in a rack if you want to work on the server hardware, even when another server is mounted directly above. It's a key part of any IT system often.
-
Retail Fiber Optic Enterprise Router PAM4
Supporting 10km over single-mode fiber with 4 CWDM lanes (1271-1331nm) using PAM4 modulation, this module provides 7. 1 dB average link budget at 425 Gbps aggregate throughput. LC/UPC duplex connector with host FEC support. In this evolving landscape, QSFP28 PAM4 DWDM (Dense Wavelength Division Multiplexing) emerges as a practical and high-performance solution for extending 100G and 400G signals across metro, campus, and inter-data-center links. In this article, we will explore the concept of QSFP28 PAM4, its benefits, and its applications in. Utilizing advanced PAM4 modulation, QSFP28 100G PAM4 DWDM transceiver supports up to 4Tb/s of bandwidth over a single fiber and the transmission distance allows for up to 80km. What Does. Twin-port OSFP single-mode transceivers house two complete multimode or single-mode optical engines inside that exit to two, 4-channel MPO-12/APC optical connectors creating the twin-ports.
[PDF Version]
-
Requirements for the Installation Location of Enterprise Distribution Boxes
Choose the right box based on environment (indoor/outdoor), load capacity, and durability. Check for proper IP/NEMA ratings and material quality. Ensure safe placement: install in dry, accessible areas with good ventilation and at appropriate height (typically ~1. According to standards, the height from the bottom edge of a distribution box to the floor is generally 1. Site selection requirements: The distribution box should be installed in an area close to the power supply to reduce. The following are some key steps and considerations to confirm whether the installation location of the box is reasonable. Check the safety of the installation location Away from moisture and corrosive environment The installation location should be away from moisture sources and corrosive. According to the "Code for Acceptance of Construction Quality of Building Electrical Engineering" GB50303-2002, the vertical distance between the bottom surface of the fixed stainless steel enclosure ip67 and the ground should be greater than 1.
[PDF Version]
-
Ai Pakistan Cloth Company
Textiles, standing out today as a leading manufacturers of quality Grieg, fabric & madeups for home and institutional textile sectors across the globe, started off in 1975 as a yarn trading company in Faisalabad for native market by our late father Haji Abdul Rasheed. Textile is a leading export textile service providers globally. The exports started in 2000 and since then we never look back and to-day A-I- Textiles which is a family run company which is running by a sec-o generation. Which have a complete vertically integrated state of the art weaving, Dyeing, and fin-ishing facilities with over, 1, any is. A. Join now the world's largest sourcing. Stay on top of your Business Credit File Get full access to view your D&B business credit file now for just $39/month! Unlock more company and contact details with your D&B Hoovers Free Trial Find and prioritize your best prospects, boost your sales productivity, and win more deals with D&B. Since its inception in 1975.
[PDF Version]